Zichen Tian

Research

Papers by Zichen Tian

PhD candidate, Singapore Management University · Google PhD Fellowship 2026 · Parameter-efficient fine-tuning, LoRA, multi-task learning, remote sensing

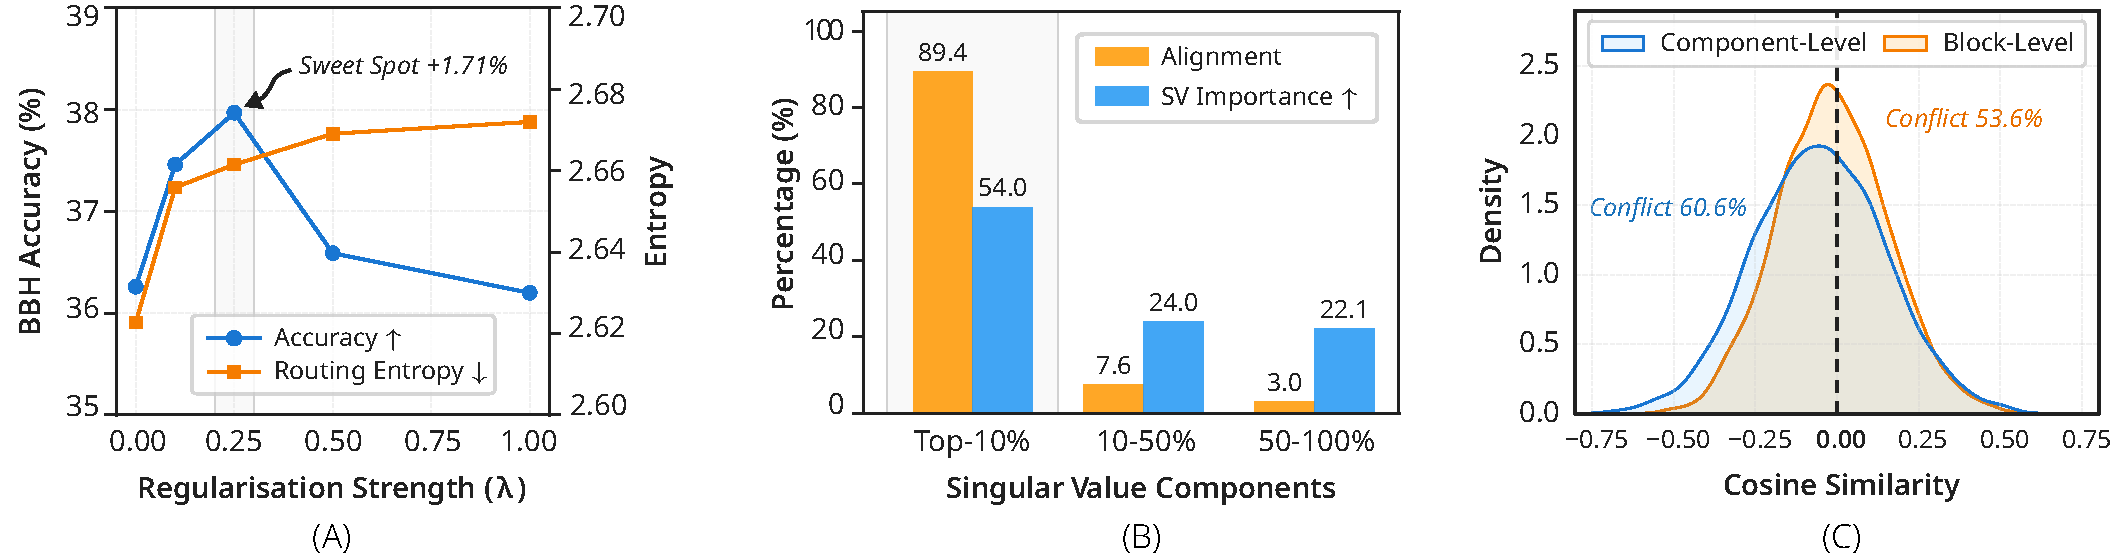
Why multi-task LoRA breaks at scale: (A) accuracy vs routing entropy under growing regularization, (B) task alignment concentrated in the top-10% singular components, (C) gradient-conflict distributions for component-level vs block-level LoRA

ICLR 2026

Scalable Multi-Task Low-Rank Model Adaptation

mtLoRA

Zichen Tian, Antoine Ledent, Qianru Sun

Scales multi-task LoRA to 15-25 tasks with Spectral-Aware Regularization, Block-Level Adaptation and Fine-Grained Routing: +2.3% over SOTA, 47% fewer parameters.

88.2 → 2.0%DOTA accuracy when plain multi-task LoRA scales from 5 to 15 tasks
+2.3%average accuracy over the previous state of the art